Solution Database / IT and Development
AI workflow evaluation service
Teams lack task-specific evidence of assistant reliability. Evaluation centered on completed customer tasks and consequential failures.
01The offer
For businesses deploying customer-facing AI assistants, turn representative tasks, reference answers and acceptance criteria into evaluation suite and actionable failure report. Address the recurring problem: teams lack task-specific evidence of assistant reliability. The value hypothesis is a more complete, reviewable deliverable with less repeated preparation; the pilot must establish whether that benefit is real.
- For
- Businesses deploying customer-facing AI assistants
- Takes in
- Representative tasks, reference answers and acceptance criteria
- Delivers
- Evaluation suite and actionable failure report
- Message
- AI workflow evaluation service for businesses deploying customer-facing AI assistants. Evaluation centered on completed customer tasks and consequential failures. Demonstrate the claim through a task-specific assistant evaluation report.
- Lead magnet
- A task-specific assistant evaluation report
02How it works
- Define task rubrics
- Create edge cases
- Replay evaluations
- Inspect source use
- Compare versions
- Track regressions
Workflow
Agree review criteria, ingest a sample, generate candidate findings, inspect supporting evidence, let reviewers confirm or dismiss each item, assign corrections, and recheck the affected material. Start with representative tasks, reference answers and acceptance criteria and finish with evaluation suite and actionable failure report.
AI and people
Propose possible inconsistencies, omissions and rubric matches. Combine extraction with deterministic checks where rules are explicit. Reviewers make the final judgment. Keep false positives and missed cases visible during evaluation.
Screens
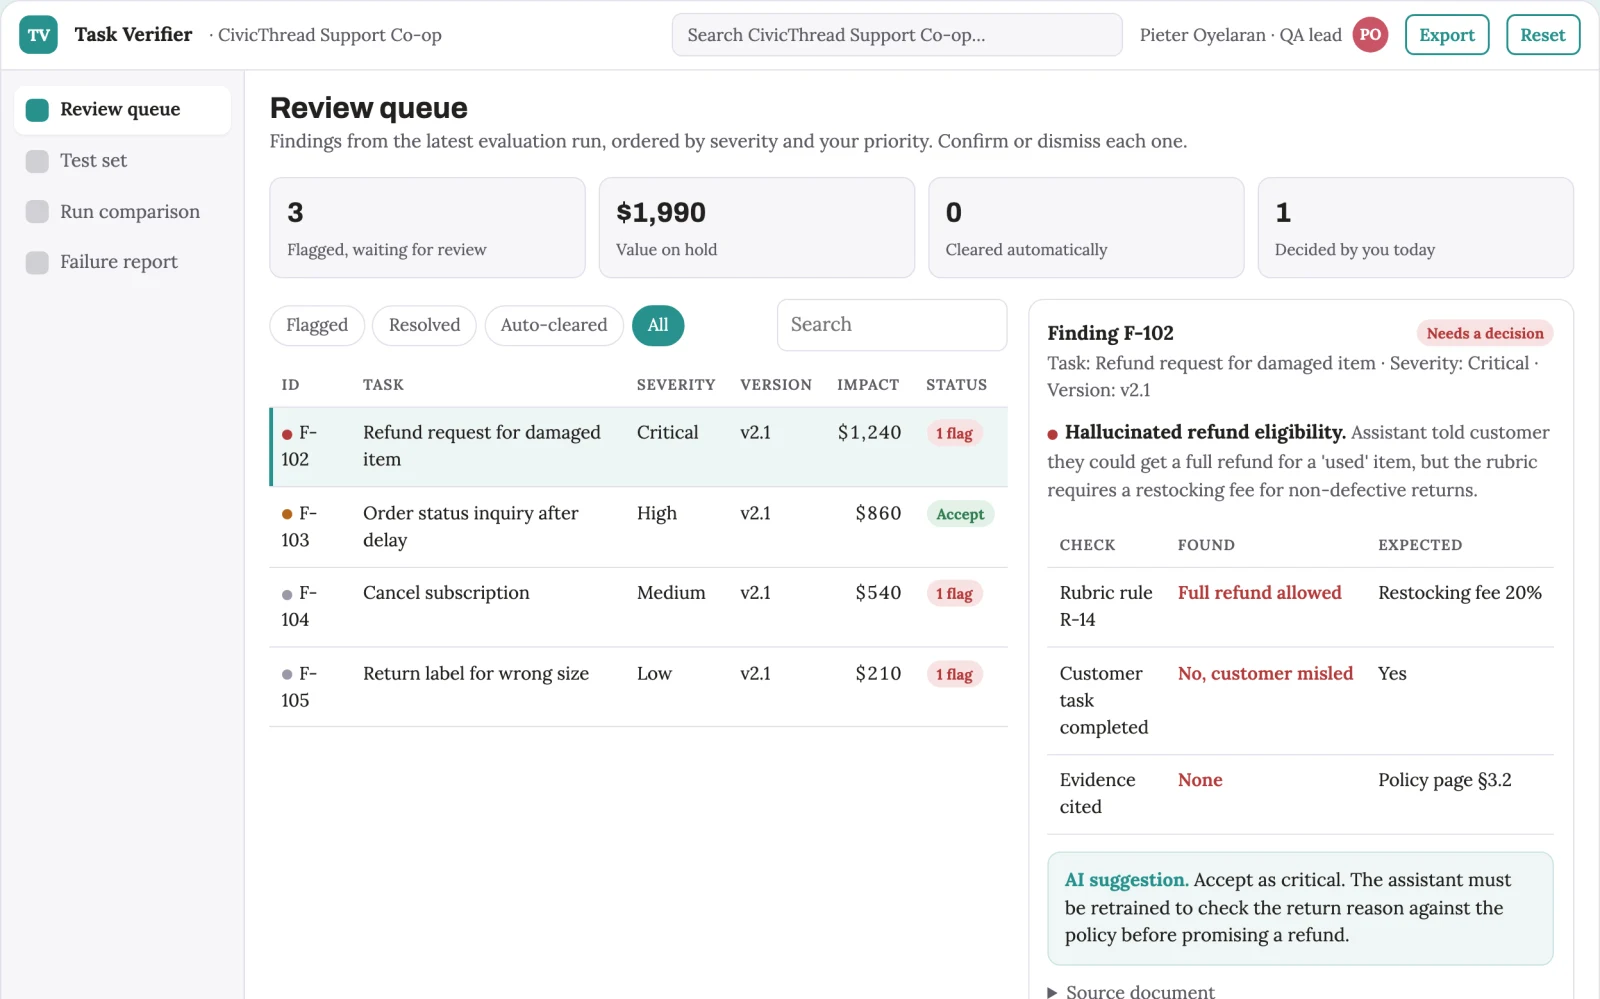
Key screens: Test set, run comparison, failure evidence. Open on a review queue ordered by reviewer-selected priorities. Show each finding beside the original evidence and applicable rule. Provide accept, dismiss and needs-information controls with reasons. A separate report view summarizes confirmed findings and unresolved items, not raw AI flags. In this product, the first view is test set, followed by run comparison and failure evidence.
Admin
Versioned review criteria, evidence links, reviewer decisions, disagreement handling, correction assignments, recheck status and exportable review history.
03Market gap
Alternatives buyers use today
Manual reviewers, checklists, generic scanning tools and specialist audit services. Differentiate on this specific proposed advantage: evaluation centered on completed customer tasks and consequential failures. Test it against the buyer's current method on the same task. Competitor coverage and uniqueness have not been established.
Where this wins
A domain-specific review rubric and rights-cleared examples of confirmed defects, false alarms and reviewer reasoning. For this solution, build around evaluation centered on completed customer tasks and consequential failures. This advantage requires execution and accumulated customer trust; the base model alone is not a defensible asset.
04Why now
IT and Development teams are adopting AI for exactly this kind of repeatable work, and the cost of language and vision models has dropped far enough that a narrow, reviewed workflow pays back quickly. The buyer already feels the problem: teams lack task-specific evidence of assistant reliability.
05Proof & signals
Channels where buyers gather: AI implementation agencies. Metrics that prove it works: Accepted task success, regression detection.
Paid pilot
Have a qualified reviewer independently assess the same sample. Compare confirmed findings, false alarms and omissions. Repeat on unseen material before agreeing recurring volume. For this solution, use representative tasks, reference answers and acceptance criteria and evaluate evaluation suite and actionable failure report. Agree success thresholds with the buyer before starting; collect a baseline for accepted task success, regression detection. A positive signal is payment and repeat use with acceptable quality and delivery cost, not a favorable demo reaction alone.
06Execution plan
MVP
Begin with businesses deploying customer-facing AI assistants and one recurring use case. Build the first two modules: define task rubrics; create edge cases. Provide operator assistance for the third module: replay evaluations. Deliver evaluation suite and actionable failure report through a manual review queue. Perform other necessary full-scope functions manually during the pilot. Include all applicable access, accuracy and professional-review controls from the start.
First 30 days
Week 1: interview five prospective buyers in this segment: businesses deploying customer-facing AI assistants. Ask to see a recent example of the problem and their current process. Week 2: prepare this demonstration using authorized or synthetic material: a task-specific assistant evaluation report. Week 3: present it through AI implementation agencies and seek one narrowly scoped paid pilot. Week 4: review accepted task success, regression detection, total delivery effort and a concrete renewal decision before increasing scope.
After the pilot
After paid pilots establish value, automate the remaining modules: inspect source use; compare versions; track regressions. Add one validated source integration, reusable customer configuration and recurring delivery. Expand to additional teams, document formats or languages only after testing the new scope.
Retention
Offer recurring reviews and rechecks of previously confirmed issues. Expand document or case types after validating the new rubric with qualified reviewers.
Integrations
Authorized repositories, technical documentation, application APIs and logs. Source repositories, task trackers and report exports. Keep findings as review proposals until authorized owners accept the resulting actions. These are candidate integration categories, not verified supported connectors.
07Investment and running costs
| Phase | Scope | Time | Budget |
|---|---|---|---|
| MVP | One buyer segment, one recurring use case; first modules: define task rubrics; create edge cases. Manual review in the loop. | 5 days | $9,000 |
| Paid pilot | Accounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers. | 6 days | $10,500 |
| Full product | Remaining modules: inspect source use; compare versions; track regressions. Self-serve onboarding, billing, monitoring and the wider integration set. | 10 days | $14,500 |
| Total | $34,000 | ||
| Running | Hosting | AI usage | Total a month |
|---|---|---|---|
| MVP and paid pilot (about 3 customers) | $30–$60 | $80–$160 | $110–$220 |
| Full product (about 50 customers) | $110–$210 | $880–$1,750 | $990–$1,960 |
Revenue model to test
Test USD 1,000-3,000 for a task-specific evaluation set and reviewed baseline report. Offer recurring release evaluations on a retainer tied to case count and review depth. Prices are hypotheses.
Cost drivers
Document or media processing, model evaluation, expert review, false-positive handling, rechecks and customer-specific rubric calibration.
Safeguards
Protect secrets, customer data and source code. Use controlled environments, technical review and a recoverable deployment process. Validate source access and reviewer availability during the pilot. Maintain customer-level access, data deletion controls and a record of final approvals.
Take it further
Concept proposal expanded from the 315-solution conversation. Demand, pricing, differentiation, build scope and integration feasibility are hypotheses, not verified market findings. Category link is inspiration rather than evidence of business viability.